September 20, 2026 · 9 min read
Streaming AI Responses: SSE, WebSockets, and the Right Transport
Streaming is a behavior, not a protocol. Here is how SSE, WebSockets, chunked HTTP, and Ollama’s model stream fit together—and how to choose without overengineering.
Streaming · SSE · WebSockets · Ollama · System Design
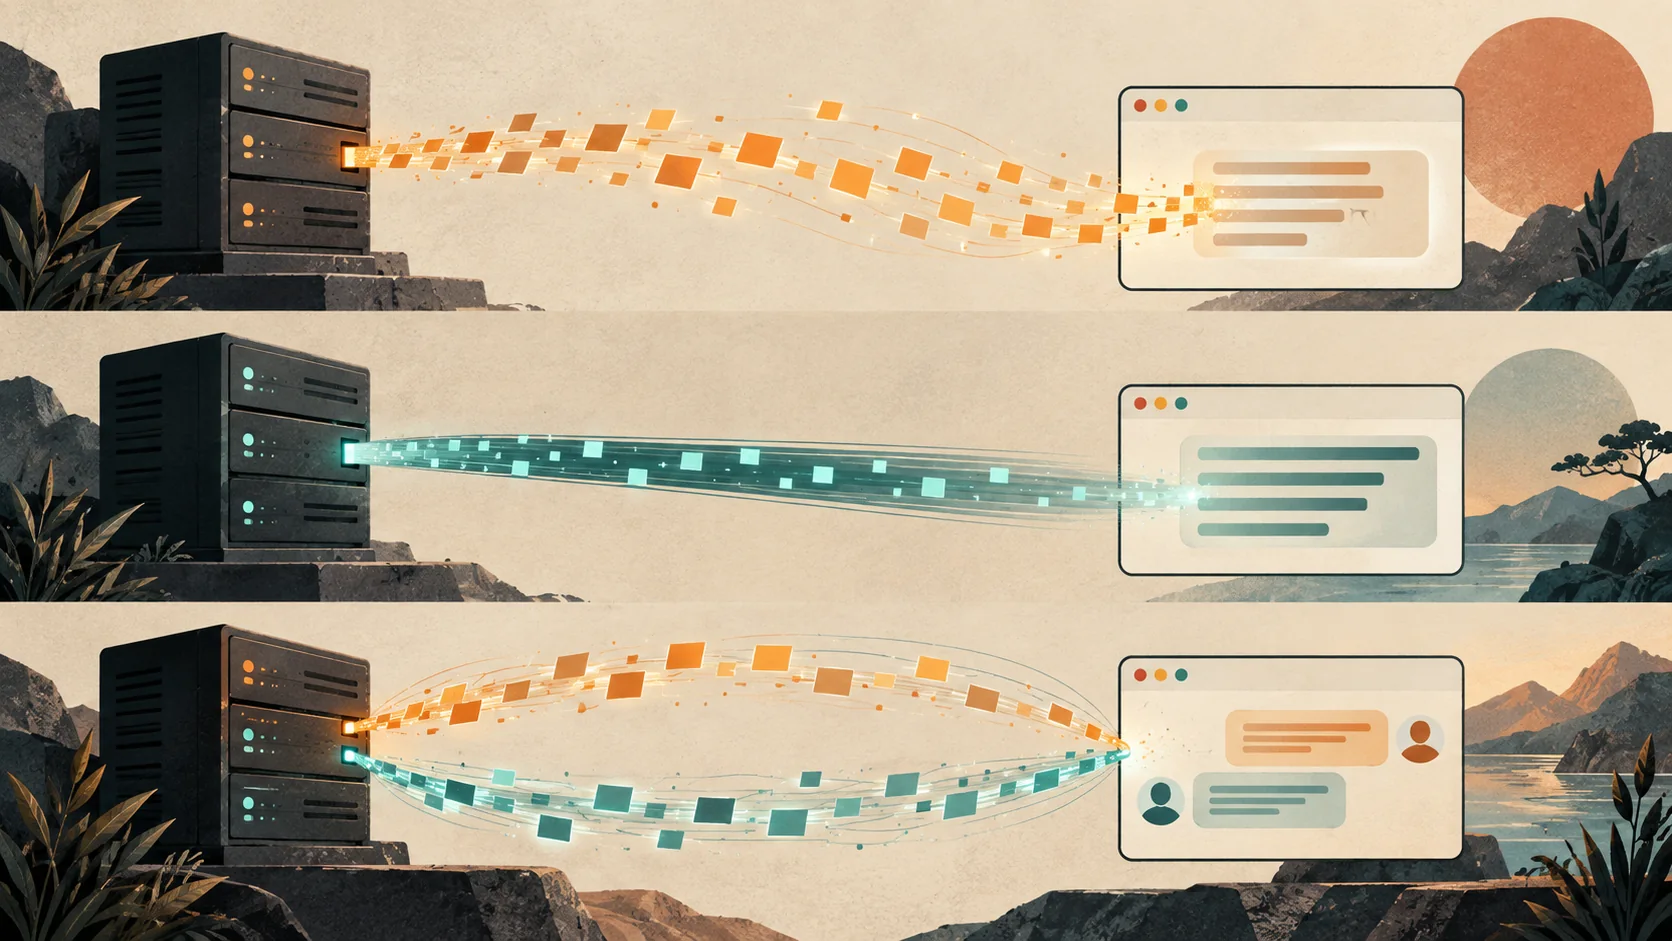
An AI response feels fast when the user sees useful output early, not merely when the last token arrives quickly. That makes transport design part of the product experience.
The crucial distinction is simple: streaming describes how results arrive; SSE and WebSockets are two of the mechanisms that can carry them.
Ollama’s native streaming API currently emits newline-delimited JSON. In the architecture below, the application gateway consumes that model stream and translates it into SSE for the browser.
Streaming is a behavior
Streaming simply means the server does not wait until the entire answer is ready before sending something back to the user.
Suppose your application asks Ollama:
Explain how a mortgage works.Without streaming, the flow looks like this:
User sends question
        |
        v
Server starts generating
        |
        |  waits...
        |  waits...
        |  waits...
        |
        v
Entire answer completed
        |
        v
Browser receives everything at once
The user may stare at an empty screen for five or ten seconds.
With streaming, the server starts sending pieces as soon as they are generated:
User sends question
        |
        v
Server starts generating
        |
        +--> "A"
        +--> " mortgage"
        +--> " is"
        +--> " a loan"
        +--> " used"
        +--> " to purchase..."
The user starts seeing the answer immediately:
A mortgage is a loan used to purchase...This is exactly the behavior you see in ChatGPT when words appear progressively.
Streaming is therefore not really a communication protocol by itself. It is a behavior: instead of sending one complete response, the server sends multiple pieces over time.
Those pieces are often called chunks, events, tokens, or messages depending on the implementation.
For AI applications, streaming is especially useful because model generation can take several seconds. Even if the full answer takes ten seconds, the first words might be available in half a second.
So the perceived performance becomes much better.
Without streaming:
10 seconds silence
↓
whole answer
With streaming:
0.5 sec
↓
first words
↓
more words
↓
more words
↓
finished at 10 sec
The total processing time might still be ten seconds. The user experience is simply much better.
Server-Sent Events
Server-Sent Events, usually abbreviated as SSE, is one specific way of implementing streaming over HTTP.
The easiest way to understand SSE is:
Browser makes one HTTP request.

Server keeps that HTTP response open.

Server sends new pieces whenever something becomes available.
Imagine your browser sends:
GET /api/chat/streamInstead of responding once and closing the connection, the server keeps it open:
Browser                           Server

   |                                |
   |------ request ---------------->|
   |                                |
   |<------ "A mortgage" -----------|
   |                                |
   |<------ " is a loan" -----------|
   |                                |
   |<------ " used to buy" ---------|
   |                                |
   |<------ " property." -----------|
   |                                |
   |<------ DONE -------------------|
   |                                |
   connection closes
That is SSE.
Technically, the server responds using:
Content-Type: text/event-streamand sends events such as:
data: A mortgage

data: is a loan

data: used to buy

data: property.
The browser receives those events one by one.
A Real AI Use Case
Suppose you build this application:
Company Knowledge AssistantThe user asks:
What is our production deployment procedure?Your frontend sends:
POST /api/chatto your AI Gateway.
Your Gateway performs RAG:
Question
   |
   v
Embedding search
   |
   v
Find deployment policy
   |
   v
Send context + question to Ollama
Ollama starts producing:
Before
deploying
to
production,
the
service
owner...
Your backend does not need to wait for Ollama to finish.
Instead, the flow can become:
Ollama
   |
   | stream chunks
   v
AI Gateway
   |
   | SSE
   v
Browser
So perhaps Ollama produces:
"Before"Your Gateway immediately sends an SSE event:
data: BeforeThen Ollama produces:
" deploying"The Gateway sends:
data: deployingThe browser keeps appending them.
The user sees:
Before deploying to production, the service owner...while Ollama is still generating the rest.
Streaming and SSE Are Not the Same Thing
This distinction is important.
Streaming is the general concept.
SSE is one technology you can use to implement streaming.
Think about transportation.
Streaming = transporting people

SSE       = using a bus
WebSocket = using a train
HTTP chunking = using a car
The goal is movement. The mechanism is different.
Similarly:
Streaming

can be implemented using:

    SSE
    WebSocket
    HTTP chunked responses
    gRPC streaming
So when someone says:
"Our application supports streaming."you still don’t know exactly how it is implemented.
When they say:
"We stream responses using SSE."now you know the transport mechanism.
Why SSE Works So Well for AI Chat
AI generation usually follows this pattern:
Client asks something
        |
        v
Server produces lots of output
        |
        v
Client receives output
Notice that most traffic after the request goes in one direction:
Server ---> ClientThat is exactly what SSE is designed for.
The browser sends one initial request, and then the server keeps pushing updates back.
An AI response naturally fits this pattern:
User:
Explain Kubernetes.

Server:
"Kubernetes..."
"is..."
"a container..."
"orchestration..."
"platform..."
Therefore SSE is commonly a very good choice for AI text generation.
Another Good SSE Use Case: Job Progress
Imagine the user uploads 5,000 documents for indexing.
The process may take several minutes.
The browser could receive:
data: {"progress":10}

data: {"progress":25}

data: {"progress":51}

data: {"progress":78}

data: {"progress":100}
Your screen can display:
Indexing documents: 78%Again, communication mainly flows from:
Server ---> BrowserSSE fits very nicely.
Another Example: Deployment Status
Suppose your DevOps application starts a deployment.
Instead of the frontend repeatedly asking:
Are you done?
Are you done?
Are you done?
Are you done?
the browser opens an SSE connection.
Then the backend sends:
Build started

Build successful

Docker image created

Deploying to Kubernetes

Pods starting

Health checks successful

Deployment complete
This is a natural SSE application.
Why Not Just Keep Calling the Server?
Without streaming, programmers sometimes implement polling.
The browser asks every two seconds:
GET /deployment/statusThen again:
GET /deployment/statusThen again:
GET /deployment/statusThis is called polling.
Conceptually:
Browser ---> Any update?
Server  ---> No.

Browser ---> Any update?
Server  ---> No.

Browser ---> Any update?
Server  ---> Yes.

Browser ---> Any update?
Server  ---> Yes.
This produces unnecessary traffic and can introduce delay.
SSE changes the model:
Browser:
Tell me whenever something changes.

Server:
Okay.

Server:
Build started.

Server:
Build complete.

Server:
Deployment started.

Server:
Deployment complete.
That is usually much cleaner.
Where SSE Is Less Suitable
SSE is mostly one-directional.
The important direction is:
Server ---> ClientThe browser can still send ordinary HTTP requests separately, but the SSE connection itself is primarily server-to-client.
Suppose you are building a multiplayer game.
You might need communication like:
Client ---> move player
Server ---> opponent moved
Client ---> fire weapon
Server ---> health changed
Client ---> send position
Server ---> new world state
Now communication is happening constantly in both directions.
SSE is less natural here.
WebSocket is usually better.
WebSocket Compared with SSE
A WebSocket creates a persistent two-way connection:
Client <==========> ServerBoth sides can send messages whenever they want.
SSE is more like:
Client -----------> Server
        initial HTTP request

Client <=========== Server
        continuous events
A simple way to remember it is:
SSE:
Server talks continuously.

WebSocket:
Both sides talk continuously.
For an Ollama chat application, SSE is often sufficient because the conversation usually looks like:
User sends one question
        |
        v
Server streams one answer
When the answer finishes, the next user message becomes another ordinary request.
When I Would Choose SSE
For applications you are likely to build, I would strongly consider SSE for things like:
LLM response streaming
RAG answer streaming
agent execution updates
document-processing progress
background job status
build/deployment logs
notification streams
monitoring events
For example, an agent might generate:
Searching documents...

Found 6 relevant documents...

Checking project database...

Calling cost calculator...

Analyzing results...

Preparing answer...
SSE can continuously send these status updates to the browser.
When I Would Choose WebSocket Instead
I would lean toward WebSocket when both sides need frequent, independent communication.
Examples include:
multiplayer games
collaborative document editing
live trading interfaces
interactive terminals
voice assistants
real-time audio
real-time telemetry control
bidirectional agent interfaces
A voice AI application is a particularly good example.
The client might continuously send:
audio
audio
audio
audio
while the server simultaneously sends:
transcript
audio response
status
tool results
That is genuinely bidirectional.
WebSocket makes more sense.
A Practical Ollama Architecture
For a normal local AI assistant, I would probably use this:
Browser
   |
   | POST question
   v
FastAPI / Go Gateway
   |
   | request
   v
Ollama
   |
   | streaming tokens
   v
Gateway
   |
   | SSE
   v
Browser
The browser might send:
Explain our deployment policy.The Gateway sends the request to Ollama.
Ollama streams:
"The"
" deployment"
" policy"
" requires"
...
Your Gateway receives those pieces and immediately forwards them through SSE.
The browser appends them into the chat window.
So there are actually two streams:
Ollama
   |
   | model stream
   v
Gateway
   |
   | SSE stream
   v
Browser
That is a very common and clean architecture.
The simplest way to remember the whole thing is this:
Streaming
= Send results gradually instead of waiting for everything.

SSE
= A simple HTTP mechanism for the server to continuously
  send those results to the browser.

WebSocket
= A persistent connection where both client and server
  can continuously send messages.
For a typical Ollama text-chat or RAG application, SSE is usually the first approach I would consider because the dominant flow is server-to-browser streaming, which is exactly what SSE is good at.
The decision in one sentence
Use the simplest transport that matches the direction of the conversation. If the browser sends one request and mostly receives a sequence of updates, SSE is usually the cleanest fit. If both sides must send independent messages continuously, use WebSockets. If incremental output adds no product value, return ordinary HTTP and keep the system simpler.
Continue the series
- Ollama in Production: The Architecture Around the Model
- From Catalog to Control Plane: Building an Ollama Model Registry
- Engineering with Ollama: A Six-Week Hands-On Course