September 20, 2026 · 14 min read
Ollama in Production: The Architecture Around the Model
Ollama is an inference runtime, not the whole application. This reference architecture separates the client, AI gateway, retrieval, tools, storage, and specialized models into governable boundaries.
Ollama · AI Architecture · RAG · Agentic AI · System Design
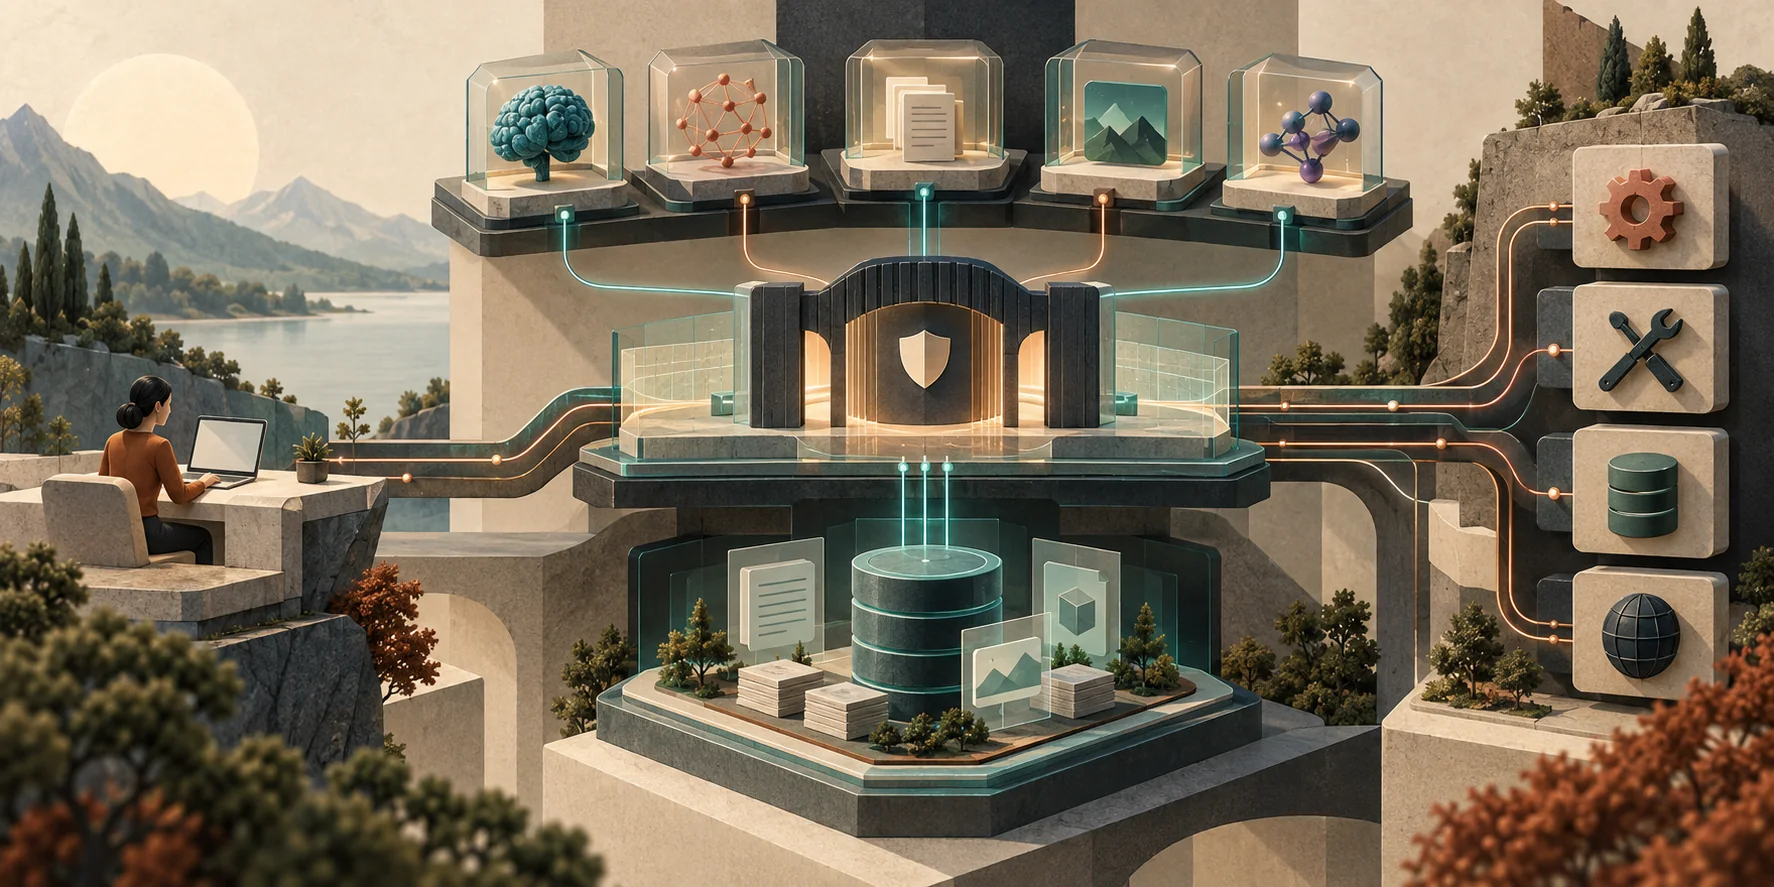
The fastest way to build a fragile local-AI application is to treat the model runtime as the application. The durable design puts Ollama behind a gateway and keeps retrieval, authorization, tools, storage, and product behavior in components you own.
What follows is a reference architecture for that separation of responsibilities.
Think of this architecture as a small company. The user talks to the front desk, the front desk gives the request to a manager, and the manager decides which specialist should handle each part of the job. Ollama is one of those specialists, but it is not the whole application. That distinction is the key to understanding the diagram.
The Client/UI
The Client/UI is whatever the user actually sees. It may be a browser application, a mobile application, a desktop application, or even another backend service.
Suppose your application is a private company knowledge assistant. The user sees a screen like this:
------------------------------------------------
Ask Company AI

[ What is our policy for production deployment? ]

                         [ Send ]
------------------------------------------------
The browser does not normally talk directly to Ollama. Instead, it sends the question to your own backend application.
For example:
POST /api/chatwith:
{
  "message": "What is our policy for production deployment?"
}
The UI is intentionally kept fairly simple. Its job is mostly to collect input, display output, maintain the visual conversation, perhaps show citations, and authenticate the user.
It should not contain your business logic.
HTTP / WebSocket
The next layer is simply how the UI communicates with your backend.
With ordinary HTTP, the flow looks like:
Browser
   |
   | POST /api/chat
   |
   v
AI Gateway
   |
   | response
   |
   v
Browser
The browser sends a request and waits for a response.
For AI applications, however, you usually want the answer to appear gradually:
The production deployment policy requires...instead of waiting ten seconds and suddenly displaying the entire answer.
That is where streaming comes in.
You can use HTTP streaming, Server-Sent Events, or WebSocket.
Conceptually:
User asks question
      |
      v
Backend starts generation
      |
      +----> "The"
      +----> " production"
      +----> " deployment"
      +----> " policy"
      +----> " requires..."
The UI displays those chunks as they arrive.
WebSocket is useful when you need two-way persistent communication, although for a basic AI chat interface it is not mandatory.
Your AI Gateway
This is the most important component in the architecture.
┌──────────────────────┐
│    Your AI Gateway   │
│   Go / FastAPI       │
└──────────────────────┘
This is your application.
Ollama is not your application.
The AI Gateway contains your rules, authentication, permissions, logging, model selection, RAG logic, tool execution rules, conversation management, auditing, error handling, and business logic.
You could write it in Go:
Browser
   |
   v
Go API
or Python:
Browser
   |
   v
FastAPI
Given a request like:
"What is the status of Project Alpha?"the Gateway has to decide what the user actually needs.
Perhaps the answer exists in company documents.
Perhaps it lives in PostgreSQL.
Perhaps the model can answer directly.
Perhaps the model needs to call an external system.
The Gateway coordinates all of this.
You can think of it as the traffic controller:
                    Question
                       |
                       v
                  AI Gateway
                       |
              What kind of job?
                       |
          +------------+-------------+
          |            |             |
          v            v             v
       Ollama      Search Docs     Call Tool
This is also where security belongs.
Suppose the user asks:
Delete Project Alpha.You should never let the model itself decide whether that operation is authorized.
The AI Gateway checks:
Who is the user?

Does this user have delete permission?

Does deletion require confirmation?

Is this tool allowed?

Should the request be audited?
Only then can the operation continue.
That is why the Gateway is so important.
Ollama
Now we arrive at Ollama:
┌───────────────────────┐
│        Ollama         │
│ localhost:11434       │
└───────────────────────┘
Ollama is basically your local AI inference server.
Your Gateway might send:
POST http://localhost:11434/api/chatand Ollama sends the request to the chosen model.
The important distinction is:
Your Gateway = application intelligence and control

Ollama = model execution/runtime
Ollama knows how to load and run models.
Your application decides why, when, and how those models should be used.
For example:
AI Gateway:
"I need a reasoning model."

        |
        v

Ollama:
"Okay. I have qwen3 loaded. I'll run it."
Ollama manages things such as model weights, inference, context, GPU memory and token generation.
Multiple Models Behind Ollama
The diagram shows three conceptual model types:
Chat Model
Embedding Model
Reasoning Model
They serve different jobs.
The Chat Model is the normal conversational model.
For example:
User:
Explain Kubernetes namespaces.

Chat Model:
A Kubernetes namespace provides...
Its primary job is generating natural-language responses.
The Reasoning Model is used when the problem requires deeper analysis.
For example:
Design a fault-tolerant distributed payment workflow
that guarantees idempotency while handling retries.
That may be routed to a stronger reasoning model.
Your gateway could therefore contain logic like:
simple question
    |
    v
fast chat model

complex architecture question
    |
    v
reasoning model
This prevents you from using an expensive or slow reasoning model for every trivial question.
The Embedding Model Is Different
The Embedding Model does not really “answer” questions.
Its purpose is to convert text into numbers.
For example:
"Production systems require two approvals."might become something conceptually like:
[
  0.024,
 -0.731,
  0.168,
  0.942,
 ...
]
Perhaps hundreds or thousands of numbers.
This numerical representation captures semantic meaning.
That means these sentences:
Production deployment requires approval.and:
Someone must authorize deployment to production.will likely produce vectors that are mathematically close to one another.
Even though the words are different, the meanings are similar.
This gives us semantic search.
Vector / Document Store
This component stores your company’s knowledge.
Imagine you have:
security-policy.pdf
deployment-runbook.md
employee-handbook.pdf
architecture.md
incident-response.md
You first break these documents into smaller pieces called chunks.
For example:
security-policy.pdf

Chunk 1
"All production access requires MFA..."

Chunk 2
"Database credentials must be stored..."

Chunk 3
"Administrative operations require..."
Each chunk goes through the Embedding Model.
Chunk
  |
  v
Embedding Model
  |
  v
Vector
Then the vector and the original text are stored together:
Vector Database

vector                     document text
----------------------------------------------------
[0.12, .43, ...]           Production access requires...
[0.55, .18, ...]           Deployment approval requires...
[0.31, .94, ...]           Database passwords must...
A common implementation could be:
PostgreSQL
+
pgvector
although many vector databases exist.
What Happens When the User Asks a RAG Question?
Now suppose the user asks:
What approvals do I need before deploying to production?This is where the entire architecture becomes interesting.
The Gateway first receives:
What approvals do I need before deploying to production?Instead of immediately asking the chat model, the Gateway sends the question to the Embedding Model.
Question

"What approvals do I need before deploying to production?"

             |
             v

       Embedding Model

             |
             v

      [0.37, 0.81, ...]
The Gateway then searches the Vector Store for document chunks with similar vectors.
The database might return:
Chunk #47
"Production deployment requires approval from the
service owner and operations lead."

Chunk #92
"Security review is required for applications that
introduce a new external integration."

Chunk #118
"Emergency deployments require incident commander approval."
These are the retrieved documents.
This process is called retrieval.
Now something very important happens.
The Gateway combines the user’s question and the retrieved material:
SYSTEM:

Answer the question using the supplied company documentation.
Do not invent information.

CONTEXT:

Production deployment requires approval from the
service owner and operations lead.

Security review is required when introducing a new
external integration.

Emergency deployment requires incident commander approval.

USER:

What approvals do I need before deploying to production?
That combined prompt is sent to the Chat Model through Ollama.
The Chat Model now answers:
For a standard production deployment, approval is required
from the service owner and operations lead.

If the deployment introduces a new external integration,
a security review is also required.

Emergency deployments require approval from the incident
commander.
That is Retrieval-Augmented Generation, or RAG.
A better representation of this part of your original diagram is actually:
User Question
     |
     v
AI Gateway
     |
     v
Embedding Model
     |
     v
Vector Store
     |
     | relevant chunks
     v
AI Gateway
     |
     | question + retrieved context
     v
Chat Model
     |
     v
Answer
The Vector Store does not normally talk directly to the Chat Model.
Your Gateway coordinates the entire process.
That is an important architectural correction to how the simple diagram appears visually.
The Tool Executor
Now consider another question:
What is the current balance of account 12345?That information probably does not belong in the language model.
It also may not exist in your vector database.
It is live transactional data.
So the model may decide:
I need to call:

get_account_balance(account_id="12345")
The Tool Executor handles that.
Model
   |
   | tool request
   v
AI Gateway
   |
   v
Tool Executor
   |
   v
Banking API / Database
Suppose the database returns:
{
    "account": "12345",
    "balance": 17854.22,
    "currency": "USD"
}
The Gateway gives that result back to the model.
Tool result:

Account 12345
Balance: $17,854.22
Currency: USD
The model converts that into a human-friendly response:
Account 12345 currently has a balance of $17,854.22.The important security principle is:
LLM says:
"I would like this tool called."

Your application says:
"Let me determine whether you are allowed to call it."
The LLM never gets unrestricted access to your operating system, database, API or filesystem.
APIs / DB / FS
The Tool Executor can communicate with many systems:
Tool Executor
      |
      +---- PostgreSQL
      |
      +---- REST API
      |
      +---- GitHub
      |
      +---- Jira
      |
      +---- Salesforce
      |
      +---- filesystem
      |
      +---- internal microservices
For example, an engineering assistant could have tools like:
get_build_status()

get_deployment_status()

search_github_issue()

get_application_logs()

restart_service()
A financial application might expose:
get_account_balance()

get_transactions()

calculate_interest()

get_customer_profile()
And an enterprise RAG application might expose:
search_documents()

get_document_metadata()

find_policy()

lookup_employee()
These are actual functions written in your application.
They are not magical abilities belonging to the model.
A Complete Example
Suppose you build an internal engineering assistant.
The user asks:
Why did the payment service fail last night,
and is there anything in our runbook describing this problem?
The browser sends the question:
Browser
   |
   v
AI Gateway
The Gateway sees that the question involves both documentation and live system information.
First it performs RAG:
Question
   |
   v
Embedding Model
   |
   v
Vector Store
   |
   v
Relevant runbook sections
Perhaps it retrieves:
If the PostgreSQL connection pool exceeds 95% utilization,
new requests may fail with connection timeout errors.
The model then requests a tool:
get_service_logs(
    service="payment",
    period="last night"
)
The Gateway checks authorization and executes it.
The Tool Executor returns:
23:42 connection pool exhausted
23:42 DB connection timeout
23:43 payment requests failed
Now the Gateway gives the model both pieces of evidence:
DOCUMENT:

If the PostgreSQL connection pool exceeds 95% utilization,
requests may fail with connection timeout errors.

LIVE LOGS:

23:42 connection pool exhausted
23:42 DB connection timeout
23:43 payment requests failed
The model can now respond:
The payment service appears to have failed because the
PostgreSQL connection pool was exhausted.

The logs show connection-pool exhaustion immediately before
the payment failures.

Your runbook describes exactly this failure mode and states
that requests may time out when pool utilization reaches
approximately 95%.
This is much more powerful than simply asking an LLM:
Why did my payment service fail?because the model is working with actual company evidence.
There Are Really Two Major Flows
Your application actually has two very different flows.
The first is the ingestion flow.
This happens before the user asks questions:
Documents
    |
    v
Read documents
    |
    v
Break into chunks
    |
    v
Embedding Model
    |
    v
Vectors
    |
    v
Vector Store
For example:
PDF
 |
 v
Extract text
 |
 v
500-token chunks
 |
 v
embeddinggemma
 |
 v
pgvector
The second is the question-and-answer flow:
User Question
      |
      v
AI Gateway
      |
      +----------> Embedding Model
      |                 |
      |                 v
      |            Vector Search
      |                 |
      |        relevant documents
      |                 |
      <-----------------+
      |
      | question + context
      v
Chat / Reasoning Model
      |
      | possibly requests tool
      v
Tool Executor
      |
      v
Actual System
      |
      v
Tool Result
      |
      v
Model
      |
      v
Final Answer
      |
      v
Client/UI
That is the architecture I would keep in your head.
Why Not Let the Browser Call Ollama Directly?
You technically could create:
Browser
   |
   v
Ollama
for a little demonstration.
But it becomes a poor application architecture very quickly.
You would have difficulty controlling authentication, authorization, tool execution, auditability, model routing, prompts, RAG, secrets, business rules, error handling, usage policies and observability.
Instead:
Browser
   |
   v
YOUR APPLICATION
   |
   v
Ollama
Your Gateway protects the rest of your architecture from the LLM.
The Most Important Mental Model
I would reduce the entire architecture to four responsibilities:
Client
    = talks to the human

AI Gateway
    = thinks about application workflow and control

Ollama
    = runs AI models

Tools + Databases
    = know the real world
And the models themselves have separate jobs:
Chat Model
    = generate language

Reasoning Model
    = analyze harder problems

Embedding Model
    = find semantically related information
The Vector Store is essentially long-term searchable knowledge:
Vector Store
    = find the right evidence
while the Tool Executor gives the system access to current reality:
RAG:
"What does our documentation say?"

Tool:
"What does the system say right now?"
That distinction becomes enormously important when building real enterprise AI applications.
A useful final picture is therefore:
                         HUMAN
                           |
                           v
                    ┌─────────────┐
                    │   Browser   │
                    └──────┬──────┘
                           |
                           v
                  ┌─────────────────┐
                  │   AI GATEWAY    │
                  │                 │
                  │ Authentication  │
                  │ Authorization   │
                  │ Conversation    │
                  │ RAG             │
                  │ Tool control    │
                  │ Model routing   │
                  │ Audit           │
                  └───┬─────────┬───┘
                      |         |
             AI work  |         | real-world work
                      |         |
                      v         v
                 ┌────────┐  ┌──────────────┐
                 │ Ollama │  │ Tool Executor│
                 └───┬────┘  └──────┬───────┘
                     |              |
             ┌───────┼───────┐      +-- DB
             |       |       |      +-- APIs
             v       v       v      +-- Files
           Chat   Reasoning Embedding
           Model    Model     Model
                               |
                               v
                         ┌────────────┐
                         │Vector Store│
                         │ Documents  │
                         └────────────┘
If you understand this picture, you already understand the basic architecture behind a large percentage of modern enterprise AI applications.
The production boundary
The model may propose. Your application must decide.
That principle governs routing, retrieval, authorization, tool execution, validation, and audit. Ollama should remain a replaceable inference dependency behind interfaces your application controls. When those boundaries are explicit, you can change models, add remote providers, or tighten policy without rewriting the product around a single runtime.
Continue the series
- From Catalog to Control Plane: Building an Ollama Model Registry
- Streaming AI Responses: SSE, WebSockets, and the Right Transport
- Engineering with Ollama: A Six-Week Hands-On Course